
Schema Markup for AI Answers: A Practical Checklist
Schema markup for AI search is not the same job it was three years ago. The structured data types that earned you rich snippets in 2022, Product, Review, BreadcrumbList, are largely irrelevant to how LLMs decide what to quote. What actually moves the needle today is a tighter set of schema types: FAQ, HowTo, Speakable, and entity-level markup that gives language models a verifiable, machine-readable identity for your content. Get those right, and your pages become source material. Get them wrong, and you're invisible to the answer layer.
Why does classic rich-snippet schema fail AI answer engines?
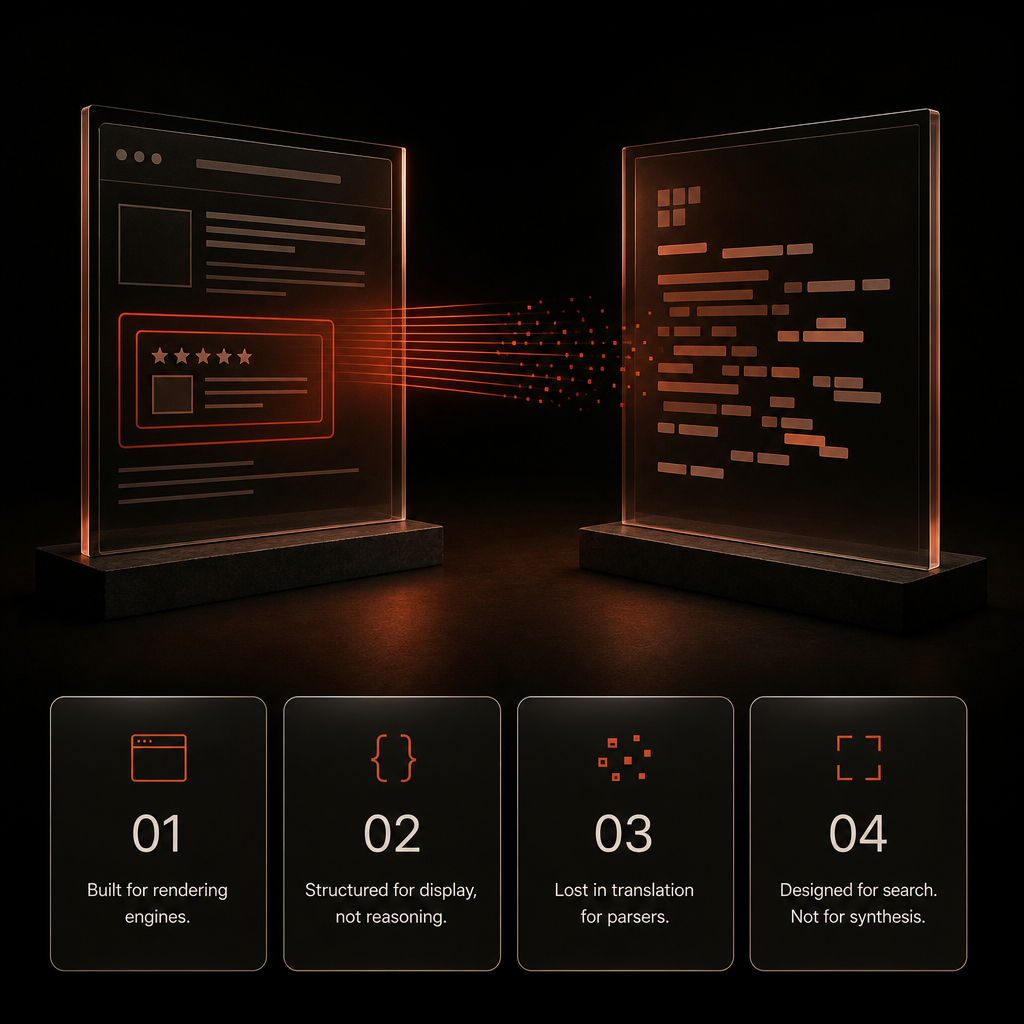
Rich-snippet schema was designed for Google's rendering engine, not for language model parsers.
Product and Review markup signals visual SERP features, star ratings, price ranges, availability panels. Those are useful for click-through on a results page. But when a language model is assembling an answer, it is not rendering a SERP. It is extracting claims, verifying entity identity, and deciding whether a source is trustworthy enough to cite.
Classic schema tells a search engine what to display. AI answer engines need schema that tells them what to believe.
That is a fundamentally different job. And most technical SEO checklists have not caught up.
What schema types actually help LLMs parse your content?
Four schema types do the heavy lifting for AI search visibility. Each solves a specific parsing problem.
FAQ schema, the citation shortcut
FAQ schema gives LLMs pre-packaged question-answer pairs they can lift verbatim.
When a language model encounters a FAQPage with Question and acceptedAnswer entities, it does not have to infer the answer from prose. The structure is explicit. The answer is bounded. The probability of accurate extraction goes up sharply.
The implementation requirement is strict: the questions must match real search queries, and the answers must be complete within the schema, not "see the section below." LLMs do not follow pointers inside structured data.
A page with three well-formed FAQ pairs, each answering a distinct long-tail query, gives an AI answer engine three discrete citation opportunities from a single URL.
HowTo schema, step-level authority
HowTo schema signals that your content is procedural, verifiable, and sequenced, which LLMs weight heavily for instructional queries.
The HowToStep entity is particularly important. Each step carries its own name, text, and optionally an image. That granularity lets a model extract step three of your process without misattributing it or conflating it with step two.
Where most implementations go wrong: they apply HowTo schema to marketing copy that describes a process vaguely. The schema says "step-by-step guide." The content says "our platform makes it easy." That mismatch reduces trust signals rather than building them.
Every step in your HowTo schema needs a concrete, self-contained action. If a reader could not complete the step from the text field alone, rewrite it before you mark it up.
Speakable schema, the voice and AI summary layer
Speakable schema tells AI systems which passages are the most authoritative, quotable summaries on a page.
Google introduced speakable for voice search, but its function maps directly to what LLMs need: a human-designated excerpt that represents the page's core claim. When you mark a passage as speakable, you are saying: "this is the sentence I want extracted."
Most pages have no speakable markup at all. That means the LLM has to guess which passage is most representative. It will often pick the wrong one, usually a sentence that is syntactically prominent but semantically thin.
Implement speakable on your lead-with-answer paragraph (the first 30-80 words of each post) and on the one-line answers under each H2. Those are the passages that answer questions directly. Mark them explicitly.
Entity schema, the trust foundation
Entity schema (using Organization, Person, Article, and sameAs properties) gives LLMs a verifiable identity graph for your content.
This is the most under-implemented schema type in most technical SEO stacks, and it has the highest leverage for AI answer visibility.
Here is why: LLMs are trained on the open web. They have prior beliefs about entities, companies, people, products, concepts. When your schema includes sameAs links to Wikidata, Crunchbase, LinkedIn, or other authoritative knowledge bases, you are connecting your content to those prior beliefs. The model can corroborate your identity claim against its training data.
A page that says "Nagent is multiplayer AI for growth" in prose is making an assertion. A page that says the same thing in Organization schema with sameAs pointing to a Wikidata entry is making a verifiable assertion. That is a different trust tier.
How do you audit your current schema for AI search gaps?
Run this checklist against every high-priority page before you write a single line of new markup.
Step 1: Inventory what you have
Use Google's Rich Results Test and Schema.org validator on your top 20 pages by organic traffic. Export the schema types present on each page.
Step 2: Flag the AI-relevant gaps
For each page, check:
Does the page answer a question? If yes, is there
FAQPageschema with at least twoQuestion+acceptedAnswerpairs?Is the page procedural? If yes, is there
HowToschema with discreteHowToStepentities, each self-contained?Does the page have a clear lead paragraph that states the core answer? If yes, is there
Speakablemarkup on that passage?Does the page reference your brand, a product, or an author? If yes, is there
Organization,Product, orPersonschema withsameAspointing to an external knowledge base?
Step 3: Check for mismatch errors
Schema that contradicts the visible content is worse than no schema. LLMs cross-reference structured data against page text. A mismatch signals either manipulation or poor maintenance, both reduce trust.
Common mismatches to catch:
FAQ schema where the
acceptedAnswertext does not appear in the page bodyHowTo schema applied to pages that are actually opinion pieces
Organizationschema with aurlproperty pointing to a redirected or dead URLsameAslinks that resolve to the wrong entity on Wikidata
Step 4: Validate entity connections
Check every sameAs URL manually. Wikidata entries get merged, deprecated, or corrected. A sameAs link to a stale or incorrect Wikidata item actively undermines your entity trust signal.
Step 5: Prioritize by query intent
Not every page needs all four schema types. Map your priority pages to the query intent they serve:
Page type: Informational / definition, Primary schema: FAQPage, Secondary schema: Speakable, Article
Page type: Tutorial / guide, Primary schema: HowTo, Secondary schema: FAQPage
Page type: Brand / about page, Primary schema: Organization, Secondary schema: Speakable
Page type: Product page, Primary schema: Product, Secondary schema: FAQPage
Page type: Author bio, Primary schema: Person, Secondary schema: sameAs
What mistakes kill schema markup for AI search?
Three implementation errors account for most of the lost AI visibility we see in audits.
Orphaned schema. Structured data added to a page that then gets redesigned, with the schema left in the old template. The markup no longer matches the content. Validators pass it; LLMs distrust it.
Generic answers in FAQ schema. Writing FAQ answers for humans reading a page, not for machines extracting a claim. "It depends on your use case" is not an acceptedAnswer. It is a deflection. Every answer must be a complete, standalone claim.
Missing @id on entities. The @id property gives your entity a canonical URI within your knowledge graph. Without it, each page's schema is an island. With it, LLMs can resolve your Organization entity across dozens of pages and build a coherent picture of who you are.
Related reading
Frequently Asked Questions
What schema markup types matter most for AI search visibility?
FAQ, HowTo, Speakable, and entity schema (Organization, Person, Article with sameAs) are the four types that directly improve how LLMs parse and trust your content. Classic rich-snippet types like Product and Review are useful for visual SERP features but do not address the trust and extraction problems that AI answer engines face.
Does schema markup guarantee that an LLM will cite my content?
No. Schema markup improves the probability that a language model can accurately extract and attribute a claim from your page. It does not guarantee citation. The content itself must answer the query directly, and the structured data must match the visible text, mismatches reduce trust rather than building it.
How often should I audit schema markup for AI search?
Audit your top 20 pages by organic traffic every quarter, and run a full-site audit every six months. Schema breaks silently: template changes, CMS updates, and content edits can all orphan structured data without triggering a visible error. Regular validation catches mismatches before they compound.
What is the sameAs property and why does it matter for AI answers?
sameAs connects your schema entity to an external knowledge base entry, typically Wikidata, Crunchbase, or LinkedIn. This lets LLMs cross-reference your identity claim against their training data. A verifiable sameAs link moves your entity from "asserted" to "corroborated" in the model's trust hierarchy, which meaningfully increases citation likelihood.
Can I implement all four schema types on a single page?
Yes, and for high-priority informational pages you should. A blog post can carry Article + FAQPage + Speakable + Organization (for the publisher) simultaneously. Use JSON-LD format and keep each type in a separate <script> block to make validation and maintenance straightforward.
What should you do next?
If you want a systematic view of where your content stack sits in the AI answer layer, the Technical SEO Audit Checklist for the Agentic AI Era is the right starting point. To see how Nagent's agents can automate structured data audits and content gap analysis at scale, book a free 30-minute demo at nagent.ai.