
Multi-Step Reasoning in AI Agents: How It Works
Multi-Step Reasoning in AI Agents: How It Works
Multi-step reasoning in AI agents means an agent plans, executes, evaluates intermediate results, and adjusts, across multiple tool calls and decision nodes, before returning a final output. This is fundamentally different from a single LLM call that generates text in one shot. The distinction matters because real GTM work, qualifying leads, drafting personalized outreach, updating CRMs, requires chains of conditional logic, not one-and-done generation.
Why Do Most "AI Agents" Still Fail at Complex Tasks?
Most AI agents today are single-shot LLM wrappers dressed up as autonomous systems.
Call an LLM, get a response, display it. That's the full loop. It works for summarization or simple Q&A. It breaks down the moment a task has more than one moving part, which is every meaningful GTM task.
Think about what qualifying an inbound lead actually involves:
Pull the lead's firmographic data from your CRM
Cross-reference against your ICP definition
Score intent signals from recent web activity
Check if an open opportunity already exists
Draft a personalized follow-up based on all of the above
A single LLM call cannot do this. It has no tools, no memory, and no ability to react to what it discovers mid-task. It guesses from whatever context fits in a prompt window.
That gap, between prompt-response and true multi-step reasoning, is where most enterprise AI deployments quietly fail.
What Is Multi-Step Reasoning in AI Agents, Exactly?
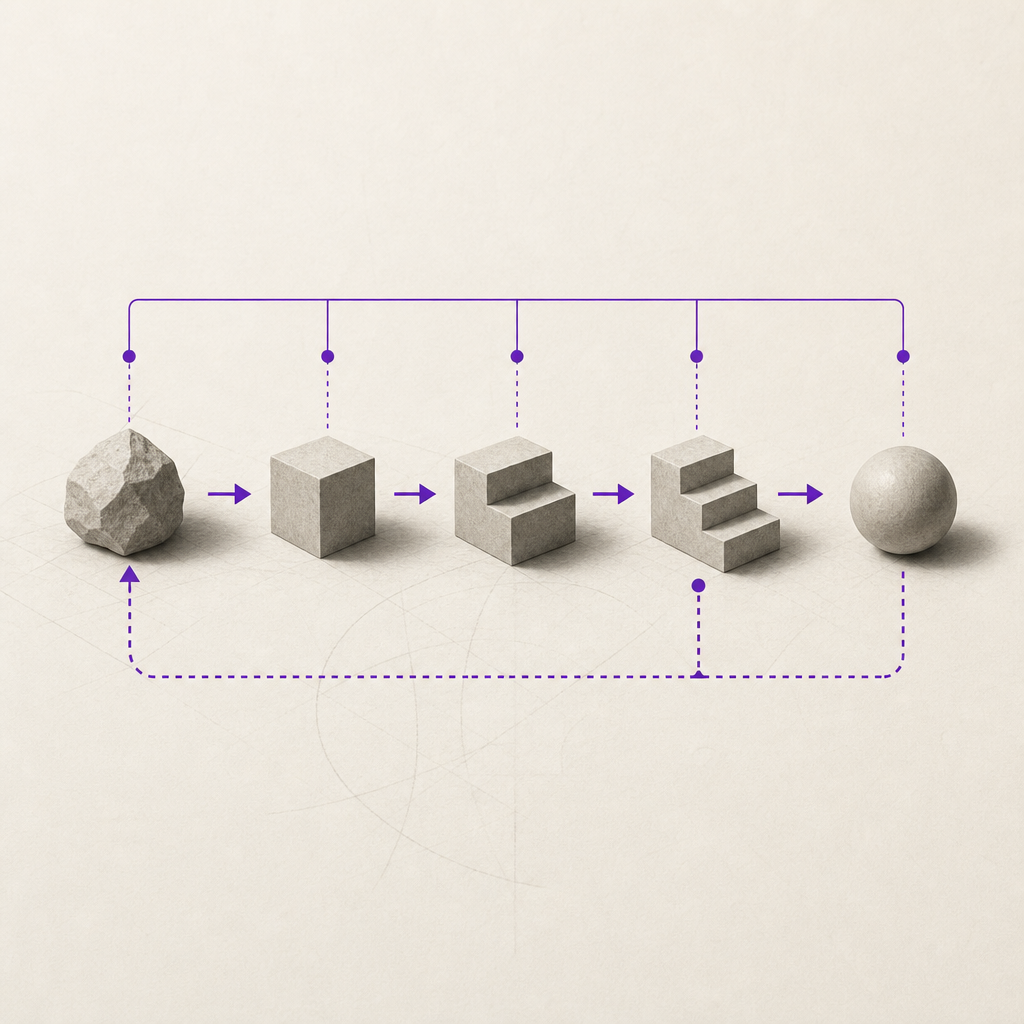
Multi-step reasoning means an agent breaks a goal into sub-tasks, executes each one, uses the output of step N as the input to step N+1, and re-plans when results don't match expectations.
It is not a prompt chain. It is not a scripted workflow.
The key elements are:
Tool calling: the agent invokes external APIs, databases, or services at each step
Intermediate state: the agent stores and reads partial results between steps
Conditional branching: if the CRM returns "duplicate lead", the agent takes a different path than if it returns "new prospect"
Memory retrieval: the agent queries past interactions to avoid repeating context it already has
Re-planning: if a tool call fails or returns unexpected data, the agent revises its approach
This is what separates automation, which follows a fixed script, from agency, which navigates uncertainty in real time.

How Does Nagent's Architecture Actually Support Multi-Step Reasoning?
On Nagent, multi-step reasoning happens inside AI teammates that work in team rooms beside your people. Three parts of the platform matter most.
Here is what each one does in a multi-step reasoning context:
Earned autonomy: trust that grows with the track record
Every step an AI teammate takes is proposed, approved, run and audited on the control plane. Teammates start supervised and are promoted level by level on their track record, so work that holds up earns more room to run without a person checking each step.
In a GTM context: if outreach drafts that reference a prospect's recent funding round keep being approved and getting replies, that record is visible to the team and counts toward the teammate's next level.
The Knowledge Hub and the team room: the context that connects steps
AI teammates answer from your Knowledge Hub, the company's own documents and decisions, and they cite their sources. Inside a team room they also share the conversation, the brief and the CRM record, so an agent on step 4 of a 6-step qualification workflow can use what step 1 found without reprocessing.
Without this, each step is blind to everything before it. With shared context, the agent reasons across the full task, and a person can see what it relied on.
Chiefs of staff: the brief becomes the plan
You do not design agent graphs on Nagent. You brief a chief of staff (MIRA for Marketing, SERA for Sales, CREA for Content) with the outcome in plain language. She plans the work into steps and hands each one to the teammate who owns it.
The plan sits in the team room before the work starts, so the people on the team can question it, change it or approve it.
What's the Difference Between a Workflow Automation Tool and a Multi-Step AI Agent?
Workflow automation follows rules. A multi-step AI agent reasons about rules.
This is a real distinction with real consequences, especially for teams already running tools like Zapier, Make, or n8n.
| Capability | Workflow Automation | Multi-Step AI Agent |
|---|---|---|
| Follows fixed scripts | ✅ | ✅ |
| Adapts when data is missing | ❌ | ✅ |
| Uses memory across tasks | ❌ | ✅ |
| Re-plans on failure | ❌ | ✅ |
| Improves with use | ❌ | ✅ |
| Requires code to change logic | Often | No |
The failure mode for workflow automation is brittleness. Change the CRM field name, and the workflow breaks. Return an unexpected API response, and the workflow stops.
A multi-step AI agent handles this differently. It treats unexpected results as information, not errors, and adjusts its next step based on what it actually received.
How Does Multi-Step Reasoning Apply to Real GTM Scenarios?
Three scenarios where multi-step reasoning produces outcomes that single-shot LLMs simply cannot match.
Scenario 1: Inbound lead qualification at scale
A Series B SaaS company receives 400 inbound leads per week. Their SDR team can meaningfully work 60.
The old approach: score by form-fill data, route to SDR, hope for the best.
The multi-step agent approach with Nagent:
Agent pulls lead data from HubSpot via tool call
Agent checks the shared record and the Knowledge Hub for past interactions with the same company or similar profiles
Agent calls a web enrichment tool to retrieve recent company news
Agent scores ICP fit against the criteria in your Knowledge Hub
Agent branches: the strongest fits go to the SDR queue with a drafted personalised opener; the rest get a context-specific nurture draft. Nothing is sent until a person approves it.
The output is not a list. It is a qualified, contextualised, actionable set of next steps, prepared at volume and waiting for a person to approve what goes out.
Scenario 2: Competitive intelligence briefing before a sales call
A solutions architect has a discovery call in 3 hours with a prospect who currently uses a competitor.
The single-shot approach: paste competitor name into ChatGPT, get generic talking points.
The multi-step agent approach:
Agent retrieves the prospect's LinkedIn activity and recent public statements via tool call
Agent checks the CRM record and the team room for earlier conversations with this account
Agent pulls the competitor's latest G2 reviews (negative sentiment prioritized)
Agent cross-references with your own differentiation notes in the Knowledge Hub
Agent drafts a 1-page briefing: prospect context, competitor weak spots, three recommended proof points
This is not summarization. It is reasoning across disparate data sources, with each step informing the next.
Scenario 3: Post-campaign attribution analysis
Marketing-ops lead needs to know which touchpoints drove pipeline last quarter. The data lives across three platforms.
A multi-step agent:
Pulls campaign data from Marketo via tool call
Pulls opportunity data from Salesforce
Joins the two datasets on contact ID
Identifies the last five touches before each opportunity creation
Clusters patterns by segment, channel, and message theme
Drafts a narrative summary with a ranked attribution model
A dashboard tool shows the data. A multi-step agent interprets it and hands back a decision.
When Should You Use a Single LLM Call Instead of Multi-Step Reasoning?
Not every task needs an agent. Single-shot LLM calls are faster and cheaper for the right use cases.
Use a single LLM call when:
The task is self-contained (summarize this email, rewrite this headline)
All required context fits in a prompt window
No external tools or data retrieval are needed
The output does not feed into a downstream action
Use multi-step reasoning in AI agents when:
The task spans multiple data sources
The logic is conditional ("if X, then Y; else Z")
Outputs from earlier steps change what later steps should do
The agent needs to verify, not just generate
The work should improve over time without manual reprogramming
The practical rule: if you would normally ask a human analyst to "figure it out as you go," you need an agent.
How Do Chiefs of Staff Enable Multi-Step Reasoning Across Teams?
Multi-step reasoning scales when agents can hand off tasks to each other.
On Nagent, a chief of staff does exactly this. Brief MIRA, the AI chief of staff for Marketing, with a complex goal, say "build a competitive go-to-market brief for our Q3 expansion into EMEA", and she plans it into sub-tasks and hands each to the teammate who owns it.
One teammate handles research. One draws on internal documents in the Knowledge Hub. One handles synthesis. A person reviews the result before it is shared.
Each teammate completes its step. The chief of staff collects the outputs, checks consistency and assembles the final deliverable in the team room.
This mirrors how a high-performing human team works, except the orchestration happens in minutes, not days.
The architecture matters here. Without true multi-step reasoning at the agent level and true orchestration at the system level, you get coordination theater, agents that look collaborative but actually run in parallel and ignore each other's outputs.
Underneath, the control plane tracks every step: which teammate did what, what was passed on, what was approved and what needs to happen next if a step fails.
What Should You Look for When Evaluating Multi-Step Reasoning in Agent Platforms?
Five questions that cut through the marketing noise when evaluating any agentic AI platform:
Does the agent actually call tools mid-task, or does it simulate tool use? Ask for a live demo with a real API call.
How does the agent handle a failed tool call? A re-planning response is a good sign. An error message is not.
Does context persist across sessions or reset every time? Ask where the agent's context comes from and whether it cites its sources.
Can you inspect the intermediate reasoning steps? Explainability is not optional in enterprise contexts.
How does the platform decide what an agent may do on its own? Look for autonomy that is earned on an inspectable track record, not just fine-tuning on request.
Most platforms pass question 1 in demos. Very few pass questions 3, 4, and 5 under scrutiny.
On Nagent, every step an AI teammate proposes is visible in the team room and recorded on the control plane, so your team can audit, adjust and trust what agents are doing, not just accept the final output.
Related Reading
Frequently Asked Questions
What is multi-step reasoning in AI agents?
Multi-step reasoning in AI agents is the ability to break a goal into sequential sub-tasks, execute each one using tools and memory, use the output of each step to inform the next, and re-plan when results are unexpected. It is different from a single LLM call, which generates a response in one pass without external tool use or intermediate evaluation. Multi-step reasoning is what allows agents to complete complex, conditional, real-world tasks autonomously.
How is multi-step reasoning different from prompt chaining?
Prompt chaining connects a fixed series of LLM calls in a predetermined sequence. Multi-step reasoning allows the agent to decide which step to take next based on what it just discovered, including calling different tools, revisiting earlier outputs, or abandoning a path that isn't working. The difference is between a script and genuine decision-making under uncertainty.
How does Nagent support multi-step reasoning?
Nagent's AI teammates reason across steps inside team rooms. Chiefs of staff (MIRA, SERA and CREA) plan the work and hand each step to the teammate who owns it, the Knowledge Hub and the team room give every step the same context, and the control plane records each action as proposed, approved, run and audited. Teammates earn autonomy level by level on their track record.
Do I need to build my own multi-step agents on Nagent?
No. Nagent is not a tool for building agents from scratch. Its AI teammates are ready to work in team rooms: you brief a chief of staff with the outcome in plain language and she plans the steps. A person approves anything that goes live.
When does multi-step reasoning actually outperform a simpler automation tool?
Multi-step reasoning outperforms rule-based automation when tasks involve missing data, conditional branching, or outputs that need to feed into downstream decisions. If a task would require a human analyst to "use their judgment" at any point, a multi-step agent will outperform a fixed workflow. For straightforward, fully predictable processes with clean data, simpler automation may be faster and cheaper.
What's Next
If your GTM team is still relying on single-shot LLM calls or brittle workflow automations for complex tasks, you are leaving accuracy and hours on the table. Book a demo and see AI teammates work through a qualification workflow, with a person approving every send.